AI ENGINEERING · GENERATIVE AI
AI Hallucinations: Why Artificial Intelligence Makes Things Up
What is an AI hallucination?
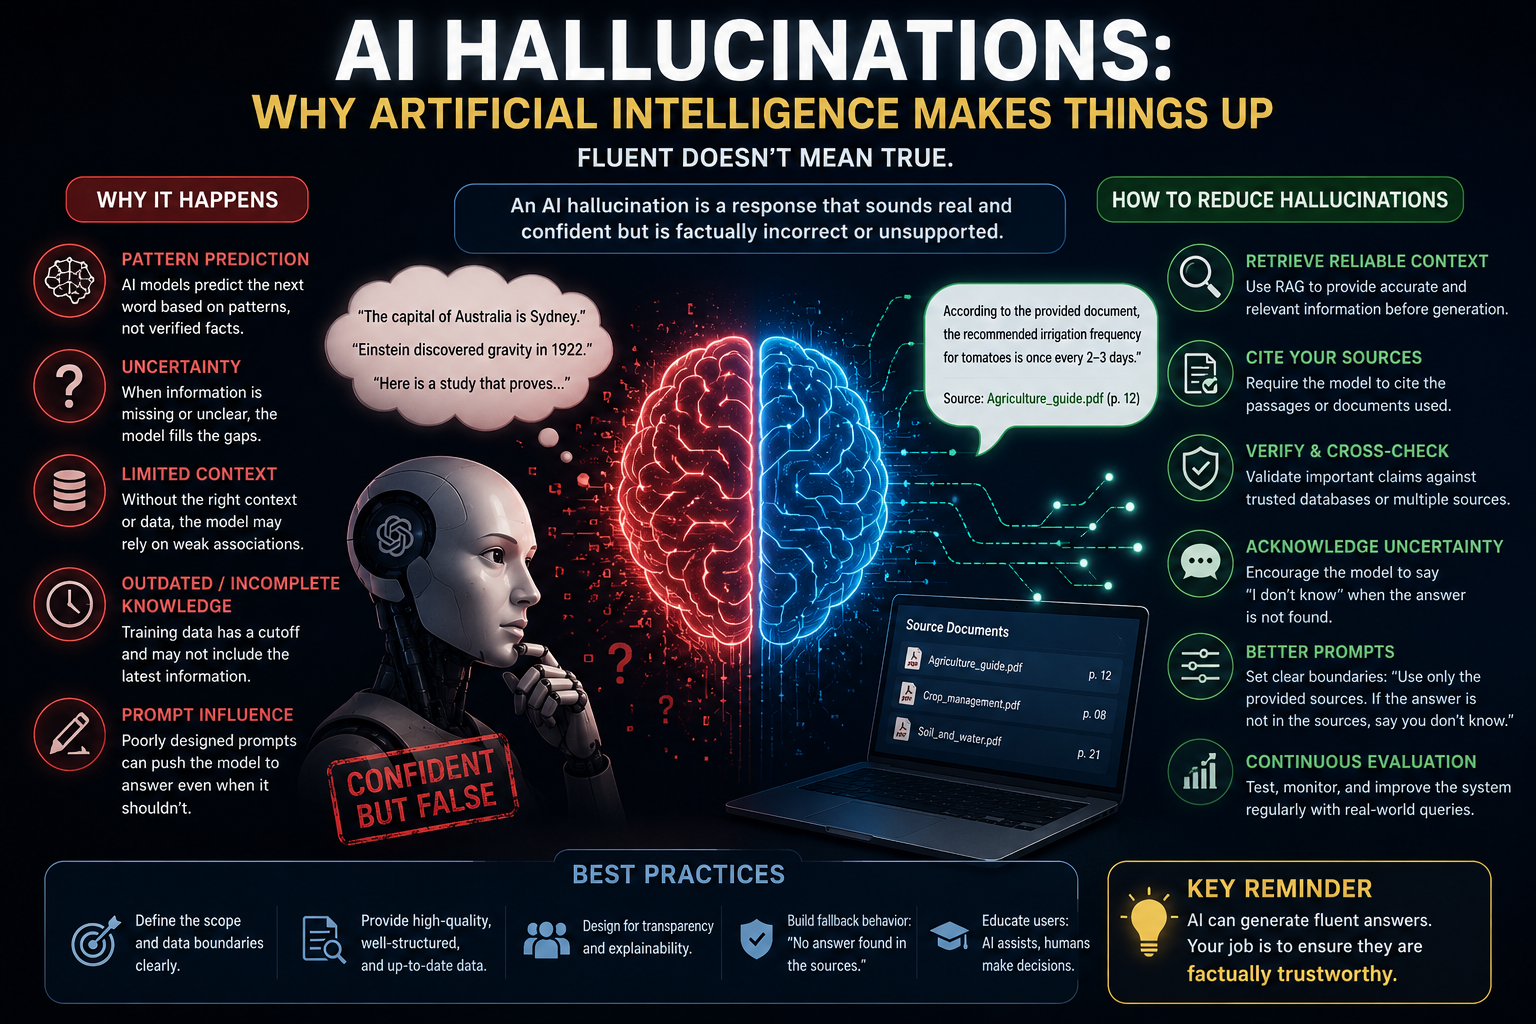
An AI hallucination is a generated statement presented as information but unsupported, inaccurate, or invented. A model may create a nonexistent citation, attribute a quotation to the wrong person, invent a product feature, or combine real facts into a false conclusion. The important point is that hallucination is not the same as an ordinary software error: the output can be grammatically correct, relevant to the question, and highly confident while still being false.
Why does artificial intelligence make things up?
Large language models are trained to learn language patterns and predict likely sequences of tokens. They do not automatically verify every statement against a trusted database before responding. When a question is ambiguous, the required information is missing, or the model has weak evidence, it can still generate a plausible continuation. In effect, fluency can survive after factual support has disappeared.
This is why a useful mental model is to treat a language model as a powerful generator rather than a built-in fact checker. It can organize information, explain concepts, summarize material, and reason over supplied context, but the reliability of a particular claim depends on the model, the prompt, the available context, and the verification process.
Are hallucinations caused only by outdated training data?
No. Outdated knowledge is one possible cause, but it is not the whole problem. A model can hallucinate even when the underlying subject is represented in its training data. The problem can arise from uncertainty, ambiguous wording, weak associations, missing context, long or complex instructions, or a request that requires a precise fact the model cannot reliably establish. A current model can therefore still produce an unsupported answer.
Why do hallucinated answers sound convincing?
Language models are optimized to produce coherent, useful-looking text. Confidence in wording is not a direct measurement of evidence. A sentence can therefore sound authoritative because its structure and vocabulary are natural, even though the claim itself has not been verified. Readers should separate two questions: “Does this sound plausible?” and “What evidence supports it?” Only the second question establishes trust.
AI RELIABILITY · ROOT CAUSES
Where Hallucinations Begin
What are the most common situations that trigger hallucinations?
Hallucinations are more likely when a system must answer beyond the evidence available to it. Typical situations include requests for obscure facts, incomplete source material, ambiguous questions, fabricated references, detailed predictions, and questions that combine several unrelated requirements. The risk also increases when a system is instructed to answer every question even when the correct response should be “I don't know.”
How does missing context affect an AI response?
Context gives a model boundaries. Without reliable context, the model may rely on learned patterns rather than evidence specific to the user's situation. For example, asking an AI assistant to explain an internal company policy without supplying the policy leaves the system with no authoritative source to consult. A good system should recognize that limitation instead of filling the gap with a guess.
Can prompt wording create hallucinations?
Yes. Prompts influence how a model approaches a task. Instructions such as “provide an answer no matter what” can encourage unsupported completion. Better prompts define the evidence boundary: use only the supplied sources, identify uncertainty, and explicitly say when the answer cannot be found. Prompting does not eliminate hallucinations, but it can reduce avoidable ones by making the expected behavior clear.
What role does retrieval-augmented generation play?
Retrieval-Augmented Generation, or RAG, connects a language model to an external knowledge source. Before generation, the system retrieves relevant passages from documents or a database and provides those passages as context. This changes the task from answering only from learned patterns to answering with reference to supplied evidence.
However, RAG does not guarantee factual accuracy. If the retriever returns irrelevant passages, the sources conflict, or the required answer is absent from the retrieved context, the model may still produce an unsupported response. The quality of the final answer therefore depends heavily on the quality of retrieval.
What are the main RAG failure points?
Poor chunking can separate a key statement from the context needed to understand it.
An embedding model may fail to represent domain-specific language accurately.
Similarity search may retrieve passages that are topically related but do not directly answer the question.
A missing re-ranking or filtering step can allow noisy context to reach the model.
If the source documents are incomplete or incorrect, retrieval cannot manufacture reliable evidence.
Does retrieving more text always lead to a better answer?
No. More context can introduce irrelevant or conflicting information. Effective retrieval aims for relevant evidence, not maximum volume. A focused set of passages that directly addresses the question is usually more useful than a large collection of loosely related text.
AI ENGINEERING · PREVENTION & VERIFICATION
How to Reduce AI Hallucinations
How can developers reduce hallucinations in production systems?
The strongest approach is layered rather than dependent on a single prompt. Developers can improve source quality, retrieval, prompting, validation, and fallback behavior together. The system should know where its information comes from, limit unsupported claims, and provide a safe response when evidence is insufficient.
Use authoritative and well-maintained source material.
Retrieve evidence before answering knowledge-dependent questions.
Design prompts that require the model to stay within the supplied context.
Ask the system to distinguish supported facts from uncertainty.
Provide citations or source references when users need to verify important claims.
Add validation rules for high-risk or structured outputs.
Provide an explicit fallback instead of forcing an answer.
Why is source quality so important?
A retrieval system can only be as trustworthy as the information it retrieves. If a knowledge base contains outdated policies, duplicate documents, contradictory versions, or poorly extracted text, the model may faithfully use the wrong evidence. Data preparation is therefore not a secondary task. Cleaning, versioning, chunking, and metadata management directly affect the reliability of the final answer.
Should an AI system always cite its sources?
Citations are valuable when users need to inspect or audit an answer, especially in enterprise, research, compliance, and knowledge-base applications. They also provide a practical reliability check: if the system cannot identify evidence supporting a claim, that claim requires additional scrutiny. A citation alone does not prove correctness; the cited source must genuinely support the statement.
What should an AI assistant say when it does not know?
A reliable assistant should have a clear fallback path when evidence is insufficient. For a document-based system, an appropriate response is: “I could not find a relevant answer in the provided documents.” This is more useful than generating a plausible but unsupported explanation. Teams should define and test this fallback behavior before deployment.
How should hallucinations be tested?
Testing should use representative questions rather than only simple demonstrations. Teams can create a set of known questions and expected answers, then measure whether the system retrieves the correct evidence and produces a supported response. Tests should include normal queries, ambiguous questions, missing-information cases, conflicting documents, and deliberately impossible requests. Evaluation should be repeated after changes to prompts, models, embeddings, retrieval settings, or source data.
What metrics matter for a RAG-based system?
Retrieval evaluation can examine precision and recall at different top-k values. Answer evaluation can measure factual correctness, completeness, citation support, and refusal quality. Operational measures such as latency and cost also matter because a system that is accurate but unusable may not be practical. The goal is to measure the complete pipeline, not just the language model.
AI GOVERNANCE · PRACTICAL TAKEAWAYS
Building AI Systems Users Can Trust
Can hallucinations ever be eliminated completely?
No system should promise zero hallucinations. Generative models operate under uncertainty, and even a carefully designed pipeline can encounter ambiguous language, missing evidence, retrieval failures, or unexpected inputs. The practical objective is to reduce unsupported answers, detect failures early, and make uncertainty visible to users.
What is the difference between a model problem and a system problem?
Some failures originate in the model's behavior, but many are system-design issues. If the wrong document is retrieved, the knowledge base is outdated, or the application forces an answer without evidence, changing the model alone may not solve the problem. Reliable AI therefore requires attention to the complete architecture: data, retrieval, prompting, generation, validation, monitoring, and user experience.
What is a practical architecture for reducing hallucinations?
A dependable knowledge-grounded workflow can follow this sequence:
Ingest trusted documents and remove obsolete or duplicate material.
Split content into meaningful chunks while preserving important context.
Create embeddings and store them in a searchable vector database.
Convert the user's question into a retrieval query and fetch relevant passages.
Optionally re-rank results to remove weak or noisy matches.
Give the selected evidence to the language model with clear grounding instructions.
Generate an answer that stays within the available evidence.
Verify important claims and return citations or a transparent fallback when evidence is missing.
What should organizations remember about AI hallucinations?
Hallucination is not simply an AI model “lying.” It is a reliability problem created by the gap between fluent generation and verified evidence. The most effective response is not to demand more confidence from the model, but to give it better information, stronger boundaries, retrieval mechanisms, evaluation, and safe failure behavior.
Conclusion
Artificial intelligence can make things up because generating plausible language is different from verifying facts. A language model may produce a polished answer even when the required evidence is absent. That behavior becomes manageable when AI systems are designed around trustworthy sources, retrieval, explicit instructions, verification, evaluation, and honest fallback responses.
RAG can substantially improve knowledge-grounded applications, but it should be treated as an architectural pattern rather than a magic solution. Accurate source data, effective retrieval, careful generation, and continuous evaluation must work together. The central principle is simple: when evidence exists, use it; when evidence is weak, communicate uncertainty; and when evidence is missing, do not invent it.